Local Models with Gemma 4
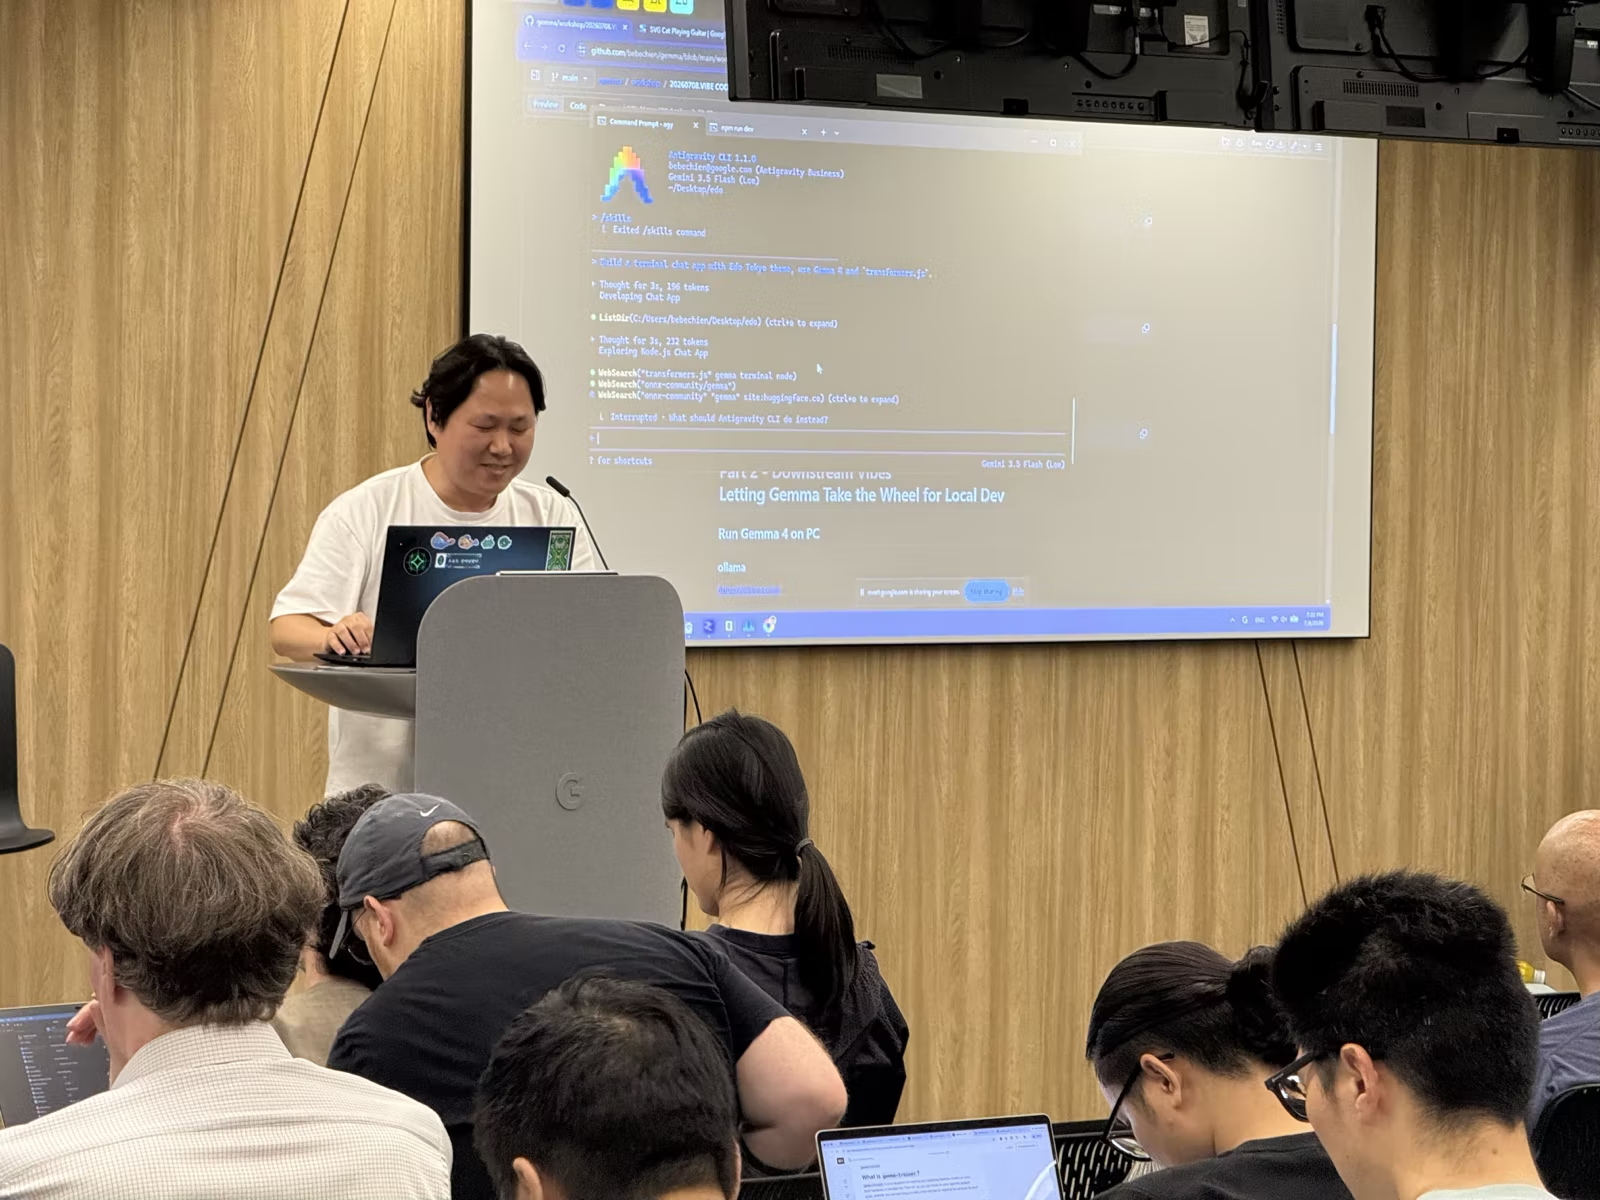
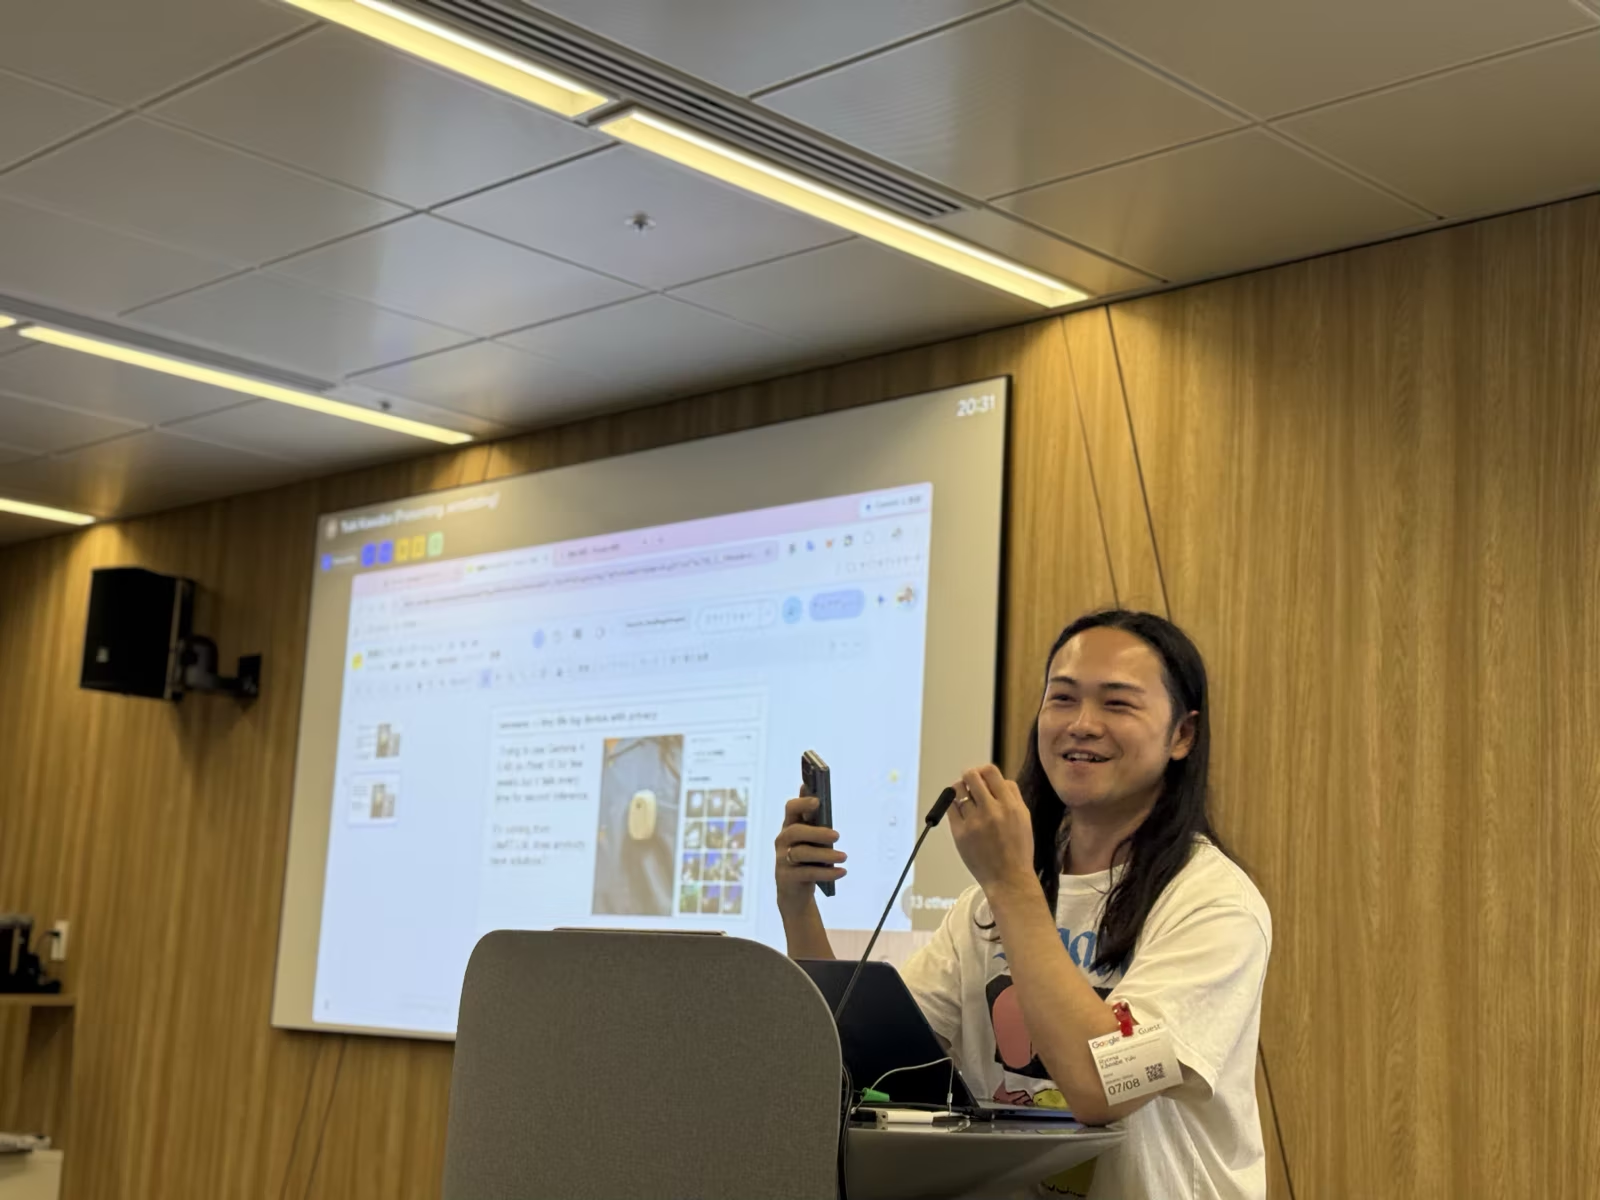
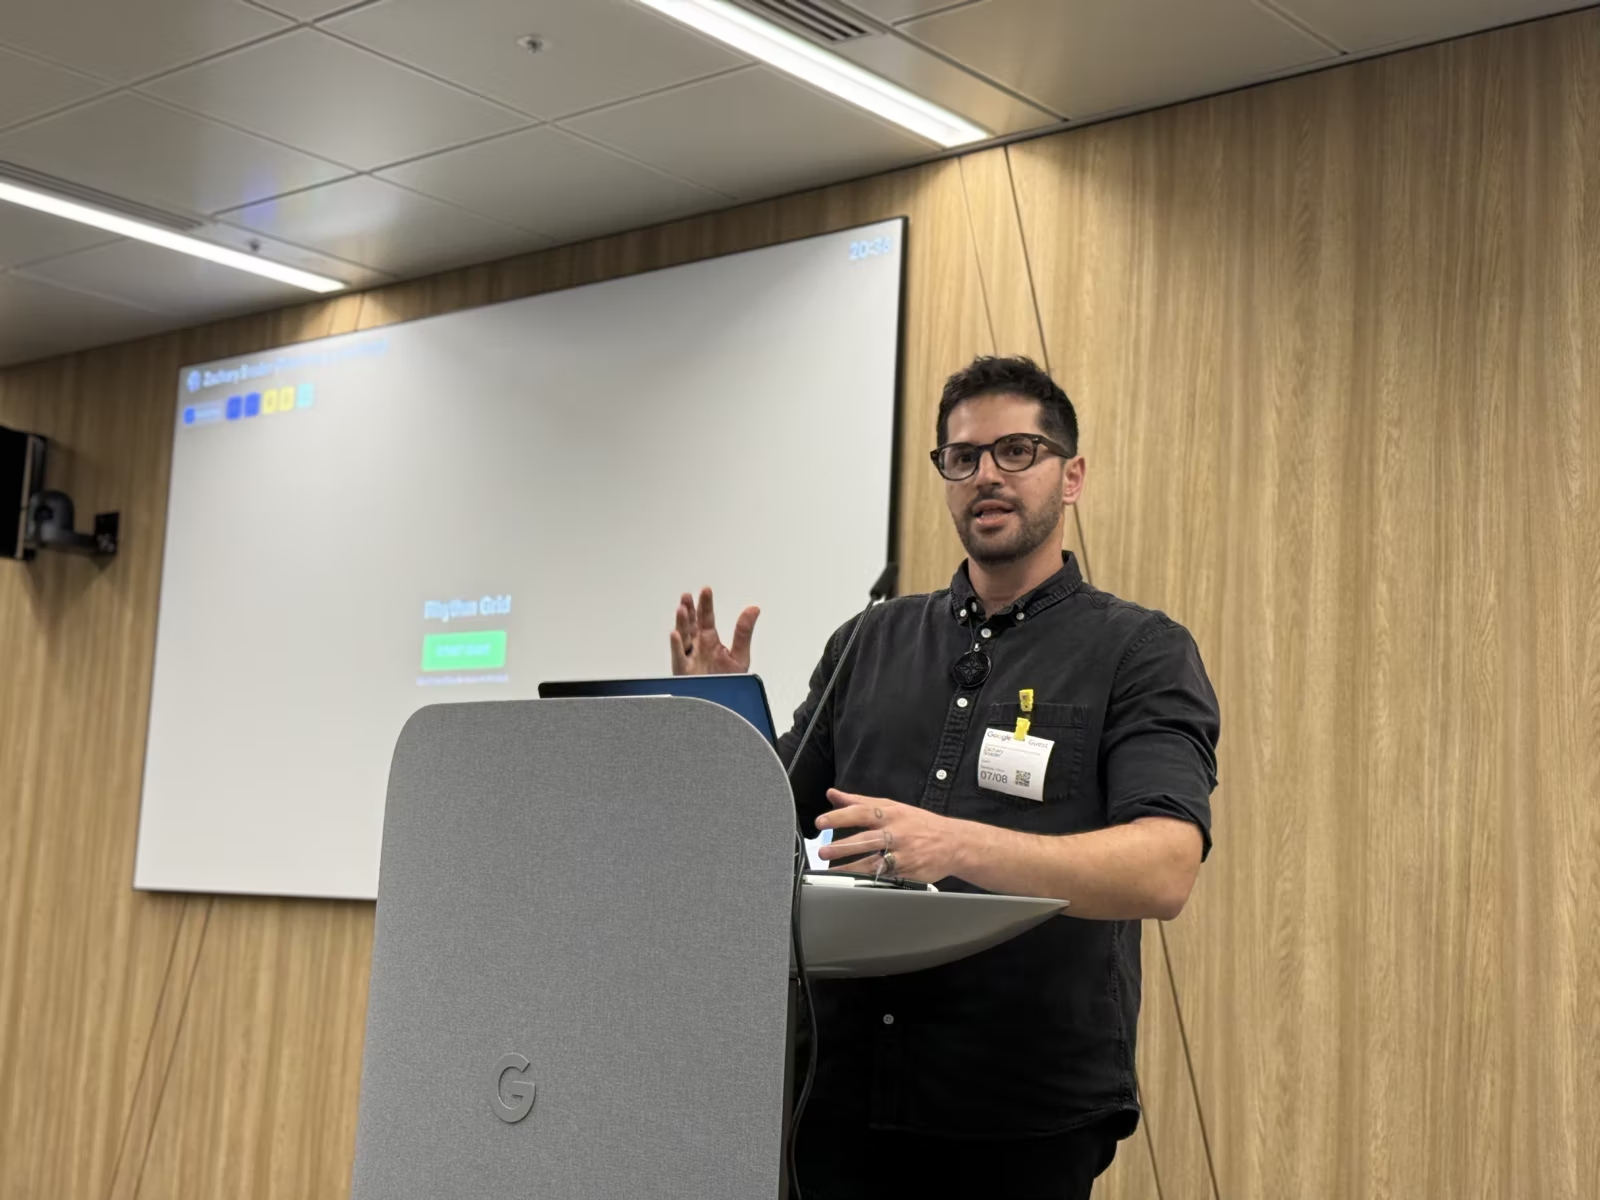
Gemma workshop, complete! 🎉 Thank you to everyone who braved the long lines to completely pack the room for our local models session! More info about the workshop.
Takeaways
-
💡 You do not need a massive GPU to start vibe coding with Gemma! You can prototype rapidly right inside Google AI Studio for free.
-
⚡ When running local models, your hardware dictates your limits. Tools like LM Studio can help you see if a model fits your GPU memory before loading it.
-
➕ Apple silicon users have a superpower here. Using MLX optimized models on an M-series Mac with high RAM lets you run incredibly smart models locally.
-
🧠 Use frontier cloud models for complex reasoning and local models for simple tasks to drastically cut your API costs.
A massive shoutout to Ju-yeong and @Alastair for dropping so much knowledge, and to our amazing volunteers for keeping the event running smoothly. The energy in the room while everyone was hacking was absolutely incredible! 🤩 ✨
Photos